
Grade F
Audited Nov 10
49 checks
SEO, GEO and AEO audit · home page score ·
SEO audit for amazon.com
amazon.com scored 45 out of 100 (grade F) in the ratemysite.ai audit of 49 checks across technical SEO, content, answer engines, AI readiness and speed, with 31 issues to fix.
Email me about this score
Compare with another site
Show your score on your site

Audit complete. This site has serious issues
Summary
Site health score
Grade F45 out of 100
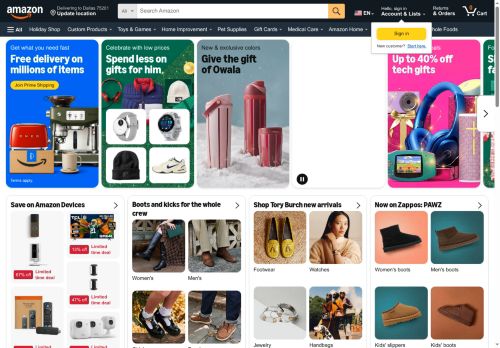
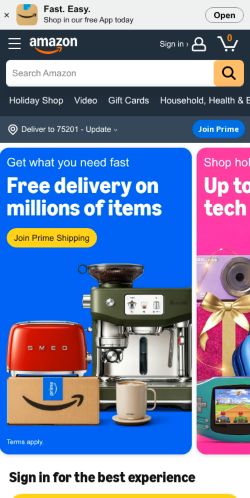
This site has serious issues. 31 things to improve.
First audit of this domain
Technical SEO
46
14 checks · 7 failed
Content
29
8 checks · 2 failed, 4 warnings
Answer engines
13
9 checks · 5 failed, 3 warnings
AI readiness
55
12 checks · 2 failed, 6 warnings
Speed
82
6 checks · 2 failed
Fix first
31 of 44 checksFailed: AI crawler accessAI readiness (GEO)
robots.txt blocks tier 1 AI crawlers: GPTBot, ClaudeBot, PerplexityBot, Google-Extended
High impactHow to fix: AI crawler access
Failed: Direct answer after the H1Answer engines (AEO)
no H1 found, so no direct-answer paragraph (0 words)
High impactHow to fix: Direct answer after the H1
Core Web Vitals
Phone, field dataLargest Contentful Paint: Passed1432 ms
Cumulative Layout Shift: Passed0.01
Interaction to Next Paint: Passed176 ms
Time to First Byte: Passed730 ms
Site health
The other pages were not scanned in this audit.
AI crawler access
2 of 16 allowedGPTBotBlockedOAI-SearchBotBlockedChatGPT-UserBlockedClaudeBotBlockedClaude-SearchBotBlockedClaude-UserBlocked
Google preview
Desktopamazon.com
amazon.com
Google will show text from the page here.
Every check, by category
Technical SEO
Technical SEO has serious issues
Whether search engines can crawl, index and understand the page: title, meta description, headings, canonical, HTTPS, robots.txt and sitemap.
Failed: Title tag lengthHigh impact
What we found
no <title> element found
Why it matters
A title tag is the page name shown as the link in search results. This check fails without a title and warns when it is under 30 or over 60 characters.
Failed: Canonical URLMedium impact
What we found
no canonical link found
Why it matters
A canonical tag is a link in the page head that names the main URL of a page. A missing tag fails, and one that points to another URL gets a warning.
Failed: Meta descriptionMedium impact
What we found
no meta description found
Why it matters
A meta description is a short summary in the page head that search results often show under your link. This check fails without one and warns below 70 or above 160 characters.
Failed: Single H1Medium impact
What we found
no H1 found
Why it matters
An H1 is the top-level heading that says what a page is about. This check passes with exactly 1 H1, fails with none, and warns when a page has 2 or more.
Failed: XML sitemapMedium impact
What we found
no sitemap found at /sitemap.xml or via robots.txt
Why it matters
An XML sitemap is a file that lists the URLs you want indexed. This check passes when the sitemap named in robots.txt, or /sitemap.xml when none is named, loads without an error. Otherwise it fails.
Failed: Internal linksMedium impact
What we found
no internal links found
Why it matters
An internal link is a link to another page on your own site. This check counts them: 0 fails, 1 or 2 gets a warning, and 3 or more passes.
Passed: Mobile viewport
viewport: width=device-width, initial-scale=1
Passed: HTML lang attribute
lang="en"
Passed: HTTPS and redirect
https with http redirecting to https
Passed: robots.txt
robots.txt present and allows crawling
Passed: Indexable (no noindex)
page is indexable
Not applicable: Heading hierarchy
no headings on the page
Not applicable: Image alt text
no images on the page
Content and E-E-A-T
Content and E-E-A-T has serious issues
Trust and depth signals: a named author, a visible date, contact and privacy pages, enough readable text and sources linked out.
Failed: Content lengthMedium impact
What we found
0 words of visible text, under 100
Why it matters
Word count is the number of words in a page's HTML body, menus and footer included. This check fails under 100 words, warns from 100 to 299, and passes at 300 words or more.
Failed: Links to sourcesMedium impact
What we found
no external links to sources (social profiles do not count)
Why it matters
An external link is a link to another website. This check counts the different sites you link to: 2 or more pass, 1 gets a warning and 0 fails. Social profiles do not count.
Warning: Contact or about pageLow impact
What we found
no contact or about page linked
Why it matters
A contact page is a page that says how to reach the people behind a site. This check passes when any link's address or text contains contact or about, and warns otherwise.
Warning: Privacy policyLow impact
What we found
no privacy policy linked
Why it matters
A privacy policy is a public page that explains what personal data a site collects and why. This check passes when any link's address or text contains privacy, and warns otherwise.
Warning: Visible dateLow impact
What we found
no visible published or updated date
Why it matters
A visible date is a line that shows when a page was updated. The check passes on a time tag, date meta tag, structured data date, or text like Updated 2026. Otherwise it warns.
Not applicable: Readability
too little text to measure readability
Not applicable: Title differs from H1
title or H1 missing, covered by other checks
Keyword consistency
The most used words on the page and where they appear.
No word appears more than once in the page text.
Answer engines (AEO)
Answer engines (AEO) has serious issues
How easily answer engines can lift an answer from the page: a direct answer up top, question headings, definitions and structured data.
Failed: Direct answer after the H1High impact
What we found
no H1 found, so no direct-answer paragraph (0 words)
Why it matters
A direct answer is a short paragraph right under the H1 that answers the page's question. This check fails under 10 words, warns from 10 to 24, and passes at 25 words or more.
Failed: FAQ schemaMedium impact
What we found
no FAQ section or FAQPage schema
Why it matters
FAQPage is a Schema.org type that marks up questions and answers as JSON-LD. This check passes with FAQPage markup, warns on an FAQ heading without it, and fails with neither.
Failed: Organization and WebSite schemaMedium impact
What we found
no Organization, WebSite or Article structured data
Why it matters
Core schema is the structured data that says who runs a site. This check needs 2 of 7 types, such as Organization and WebSite: 1 gets a warning and 0 fails.
Failed: Data pointsMedium impact
What we found
0 data points: no years, percentages, amounts or measured quantities in the text
Why it matters
Data density is a count of the hard facts in your text, such as years, prices and percentages. This check passes at 5 data points, warns at 1 to 4, and fails at 0.
Warning: DefinitionsLow impact
What we found
no definition-style sentence ("X is a ...")
Why it matters
A definition is a sentence that says what a term is, in the form X is a category. This check passes when the page has one and warns when it has none.
Warning: Lists and tablesLow impact
What we found
0 lists, 0 tables in the main content; structure helps answer engines quote you
Why it matters
Structured content is text set out as lists or tables. This check passes when the main content has at least 1 list or table outside the menu, header, footer and sidebar, and warns otherwise.
Warning: Question-style headingsLow impact
What we found
no H2 or H3 phrased as a question
Why it matters
A question heading is an H2 or H3 written as the question its section answers. The check passes if one ends in a question mark or starts with a word like how or what.
Not applicable: HowTo schema
no step list on the page
AI readiness (GEO)
AI readiness (GEO) has serious issues
Whether AI assistants such as ChatGPT, Claude and Perplexity can reach, read and cite the site: crawler access, llms.txt and content that works without JavaScript.
Failed: AI crawler accessHigh impact
What we found
robots.txt blocks tier 1 AI crawlers: GPTBot, ClaudeBot, PerplexityBot, Google-Extended
Why it matters
AI search crawlers like OAI-SearchBot, Claude-SearchBot and PerplexityBot fetch pages for ChatGPT, Claude and Perplexity search answers. If robots.txt blocks them, your pages can drop out of those answers. Blocking training bots alone does not.
Failed: llms.txtHigh impact
What we found
no /llms.txt
Why it matters
llms.txt is a plain Markdown file at the root of your site. It tells AI assistants what your site is about and which pages matter most. Writing one takes about 10 minutes.
Warning: Brand name consistencyLow impact
What we found
no og:site_name or WebSite/Organization name; AI engines cannot confirm the brand name
Why it matters
Brand consistency means spelling your site name the same way everywhere. This check compares your title tag, og:site_name and Organization schema. Matching names help search engines and AI assistants link every mention to you.
Warning: ai.txtLow impact
What we found
no /.well-known/ai.txt
Why it matters
ai.txt is a plain text file that states how AI systems may use your content. It lives at /.well-known/ai.txt. It is optional and support is uneven, but some crawlers and agents read it.
Warning: Cache headersLow impact
What we found
Cache-Control "no-store, max-age=0" prevents caching
Why it matters
Cache headers are HTTP headers that tell browsers, CDNs and crawlers how long a page stays fresh. Good headers let crawlers recheck pages cheaply. This check looks for a Cache-Control max-age, an ETag or Last-Modified.
Warning: Citable entity linksLow impact
What we found
no sameAs links (Wikipedia, LinkedIn, Crunchbase) in structured data
Why it matters
sameAs links are profile URLs listed in your Organization schema, such as LinkedIn or Wikidata. They let search engines and AI assistants confirm who you are. This check looks for at least 1.
Warning: llms-full.txtLow impact
What we found
no /llms-full.txt (optional, gives AI the full content in one file)
Why it matters
llms-full.txt is an optional companion to llms.txt that holds the full text of your key pages. AI assistants can load it in one request. This check looks for it at your site root.
Warning: Markdown versionLow impact
What we found
no Markdown version via Accept: text/markdown (optional)
Why it matters
A Markdown version is a plain text copy of a page that your server returns when an AI agent asks for text/markdown. This check sends 1 such request and looks for a Markdown reply.
Passed: Content without JavaScript
0 words available without JavaScript
Passed: No paywall or interstitial
no paywall or interstitial detected
Passed: X-Robots-Tag for AI
no AI restriction in X-Robots-Tag
Passed: HTML size
HTML is 2 KB
Speed
Speed is good
How fast the page loads and responds on a phone, from Google PageSpeed and real Chrome user data when Google has it.
Failed: Page weightMedium impact
What we found
| Metric | This page | Good | Source |
|---|---|---|---|
| Page weight | 6520 KB | 1465 KB or less | PageSpeed field data |
Why it matters
Page weight is the total size of every file a page downloads, such as images, scripts and fonts. This check passes at 1.5 MB or less, warns up to 3 MB and fails above that.
Failed: Request countMedium impact
What we found
| Metric | This page | Good | Source |
|---|---|---|---|
| Request count | 206 requests | 50 requests or less | PageSpeed field data |
Why it matters
Request count is the number of files a page fetches, such as images, scripts and fonts. This check passes at 50 requests or fewer, warns up to 100 and fails above 100.
Passed: Largest Contentful Paint
Largest Contentful Paint 1432 ms (field data)
Passed: Interaction to Next Paint
Interaction to Next Paint 176 ms (field data)
Passed: Cumulative Layout Shift
Cumulative Layout Shift 0.01 (field data)
Passed: Time to First Byte
Time to First Byte 730 ms (field data)
Site details
Technology
Software and libraries we could identify from the page and its headers.
- Cloudflare(CDN)
- Amazon CloudFront(CDN)
Social
Profiles linked from the page, and tracking pixels.
- FacebookNot linked
- InstagramNot linked
- X (Twitter)Not linked
- LinkedInNot linked
- YouTubeNot linked
- TikTokNot linked
- PinterestNot linked
- Tracking pixelsNone found
Local SEO
Only matters for businesses with a place customers visit.
- Phone on the pageNot found
- Address on the pageNot found
- LocalBusiness schemaNot found
- Google Maps or Business Profile linkNot found
Site insights
What we found on the page beyond the checks. None of it changes the score.
AI crawler access
Which AI crawlers your robots.txt lets in, and the rule that decides.
2 of 16 allowed, 14 blocked, 0 partly blocked
GPTBotOpenAIBlockedCollects content to train OpenAI models
Disallow: /OAI-SearchBotOpenAIBlockedIndexes pages for ChatGPT search answers
Disallow: /ChatGPT-UserOpenAIBlockedFetches a page when a ChatGPT user asks for it
Disallow: /ClaudeBotAnthropicBlockedCollects content to train Claude models
Disallow: /Claude-SearchBotAnthropicBlockedIndexes pages for Claude search answers
Disallow: /Claude-UserAnthropicBlockedFetches a page when a Claude user asks for it
Disallow: /PerplexityBotPerplexityBlockedIndexes pages for Perplexity answers
Disallow: /Perplexity-UserPerplexityBlockedFetches a page when a Perplexity user asks for it
Disallow: /Google-ExtendedGoogleBlockedA control token, not a crawler: tells Google whether Gemini may use your content
Disallow: /Applebot-ExtendedAppleAllowedA control token, not a crawler: tells Apple whether its AI models may use your content
Disallow: /exec/obidos/account-access-login(applies to all crawlers)AmazonbotAmazonAllowedIndexes pages for Alexa and Amazon answers
Disallow: /exec/obidos/account-access-login(applies to all crawlers)meta-externalagentMetaBlockedCollects content for Meta AI
Disallow: /CCBotCommon CrawlBlockedBuilds the open web dataset many AI models train on
Disallow: /BytespiderByteDanceBlockedCollects content for ByteDance AI models
Disallow: /DuckAssistBotDuckDuckGoBlockedFetches pages for DuckDuckGo AI answers
Disallow: /MistralAI-UserMistralBlockedFetches a page when a Le Chat user asks for it
Disallow: /
ChatGPT-User, Claude-User, Perplexity-User and MistralAI-User fetch pages when a person asks, and may not follow robots.txt rules.
Let AI assistants reach you
These crawlers are blocked. Blocking training crawlers can be a deliberate choice; to let AI assistants find and cite your pages, add these lines to your robots.txt:
User-agent: GPTBot
Allow: /

User-agent: OAI-SearchBot
Allow: /

User-agent: ChatGPT-User
Allow: /

User-agent: ClaudeBot
Allow: /

User-agent: Claude-SearchBot
Allow: /

User-agent: Claude-User
Allow: /

User-agent: PerplexityBot
Allow: /

User-agent: Perplexity-User
Allow: /

User-agent: Google-Extended
Allow: /
Google search preview
An approximate preview of how this page can look in Google results.
amazon.com
amazon.com
Google will show text from the page here.
amazon.com
amazon.com
Google will show text from the page here.
- No title found. Google will write one itself.
- No meta description found. Google will pick text from the page.
Google PageSpeed
Google's lab test of this page on a phone and on a desktop.
| Metric | Phone | Desktop |
|---|---|---|
| Google score | 69 | 58 |
| First Contentful Paint | 3.6 s | 770 ms |
| Speed Index | 5.8 s | 1.8 s |
| Largest Contentful Paint | 5.3 s | 1.2 s |
| Time to Interactive | 12.4 s | 2.8 s |
| Total Blocking Time | 13 ms | 601 ms |
| Cumulative Layout Shift | 0.00 | 0.26 |
Phone opportunities
- Render-blocking requestsEst savings of 1,480 ms
- Improve image deliveryEst savings of 306 KiB, saves about 600 ms
- Font displayEst savings of 50 ms
- Use efficient cache lifetimesEst savings of 70 KiB
- Minimize main-thread work2.2 s
- Avoid enormous network payloadsTotal size was 6,520 KiB
- Image elements do not have explicit width and height
- Reduce unused CSSEst savings of 213 KiB
Desktop opportunities
- Reduce JavaScript execution time1.9 s, saves about 600 ms
- Minimize main-thread work3.7 s, saves about 600 ms
- Render-blocking requestsEst savings of 370 ms
- Font displayEst savings of 120 ms
- Improve image deliveryEst savings of 497 KiB, saves about 100 ms
- Avoid large layout shifts3 layout shifts found, saves about 0 ms
- Use efficient cache lifetimesEst savings of 3 KiB
- Legacy JavaScriptEst savings of 6 KiB
Page weight (phone)
| Type | Requests | Size |
|---|---|---|
| Total | 203 | 6.4 MB |
| Media | 4 | 3.9 MB |
| Script | 34 | 797 KB |
| Image | 72 | 704 KB |
| Font | 17 | 493 KB |
| Document | 3 | 352 KB |
| Other | 60 | 126 KB |
| Stylesheet | 13 | 92 KB |
JavaScript errors (desktop)
15 errors in the browser console, first 10 shown.
- console.error: Error logged with the Track&Report JS errors API(http://tiny/1covqr6l8/wamazindeClieUserJava): {"m":"Found no value in attribute data-clientData under card root. Please assign in server.","csm":"v5 ue
- console.error: Error logged with the Track&Report JS errors API(http://tiny/1covqr6l8/wamazindeClieUserJava): {"m":"Found no value in attribute data-clientData under card root. Please assign in server.","csm":"v5 ue
- console.error: Error logged with the Track&Report JS errors API(http://tiny/1covqr6l8/wamazindeClieUserJava): {"m":"Found no value in attribute data-clientData under card root. Please assign in server.","csm":"v5 ue
- console.error: Error logged with the Track&Report JS errors API(http://tiny/1covqr6l8/wamazindeClieUserJava): {"m":"Found no value in attribute data-clientData under card root. Please assign in server.","csm":"v5 ue
- console.error: Error logged with the Track&Report JS errors API(http://tiny/1covqr6l8/wamazindeClieUserJava): {"m":"Found no value in attribute data-clientData under card root. Please assign in server.","csm":"v5 ue
- console.error: Error logged with the Track&Report JS errors API(http://tiny/1covqr6l8/wamazindeClieUserJava): {"m":"Found no value in attribute data-clientData under card root. Please assign in server.","csm":"v5 ue
- console.error: Error logged with the Track&Report JS errors API(http://tiny/1covqr6l8/wamazindeClieUserJava): {"m":"Found no value in attribute data-clientData under card root. Please assign in server.","csm":"v5 ue
- network: Failed to load resource: net::ERR_CONNECTION_FAILED
- network: Failed to load resource: net::ERR_TIMED_OUT
- network: Failed to load resource: the server responded with a status of 400 (Bad Request)
Headings
No headings found on this page.
Links on this page
0 links: 0 internal, 0 external, 0 nofollow.
No problem links found.
Email security
SPF and DMARC records stop others from sending email that pretends to come from this domain.
- SPFFound: only the listed servers may send email (strict)
v=spf1 include:spf1.amazon.com include:spf2.amazon.com include:amazonses.com -all - DMARCFound: fake emails go to spam
v=DMARC1;p=quarantine;pct=100;rua=mailto:report@dmarc.amazon.com;ruf=mailto:report@dmarc.amazon.comat _dmarc.amazon.com
Score history
The overall score of each audit of this site, oldest first.
First audit of this domain
Questions about this report
What is the SEO score of amazon.com?
amazon.com scored 45 out of 100, grade F, with technical SEO 46, content 29, answer engines 13, AI readiness 55 and speed 82.
What should amazon.com fix first?
Start with AI crawler access: robots.txt blocks tier 1 AI crawlers: GPTBot, ClaudeBot, PerplexityBot, Google-Extended. This report has 31 issues to fix in total.
How is the site health score calculated?
Site health is a score from 0 to 100 that combines five category scores. Technical SEO counts for 25%, content counts for 15%, answer engines counts for 20%, AI readiness counts for 25% and speed counts for 15%.
How often can this report be updated?
A new audit can run 24 hours after the last one. To run it, use the Re-analyze button at the top of this page.
Is this audit free?
Yes. Audits are free and need no account.